I build the infrastructure that serves AI in production, and cut what it costs to run.
Models on GPU, retrieval and voice pipelines, and the Kubernetes and Terraform underneath all of it. I have taken a third off one AWS bill and sixty percent off another, and I write the Python that runs on what I build. Currently Platform Engineer at Ccript.
- AWS
- GCP
- Kubernetes
- Terraform
- Python
- FastAPI
- Prometheus
- RAG / LLM
- AWS spend removed
- 30%
- AWS spend removed
- Autoscaling and ECS right-sizing, at 1M+ users
- Faster catalog search
- 787×
- Faster catalog search
- 6,456 ms to 8.2 ms on 25,631 products
- Cheaper after migration
- 60%
- Cheaper after migration
- AWS to bare metal, zero customer downtime
- Uptime sustained
- 99.9%
- Uptime sustained
- 20K to 30K concurrent at peak load
Six systems worth reading about
Five of the six are running in production today. Every number below was measured, not estimated.
GPU inference platform
The layer between a chosen model and a served one. Models deploy onto pooled GPU nodes, scale with real demand, report on themselves, and can be benchmarked against each other under the same load before anyone commits capacity to one.
- vLLM runtime
- GPU autoscaling
- Kubernetes
- vLLM
- Python
- GPU
- Helm
- Prometheus
SmartZees
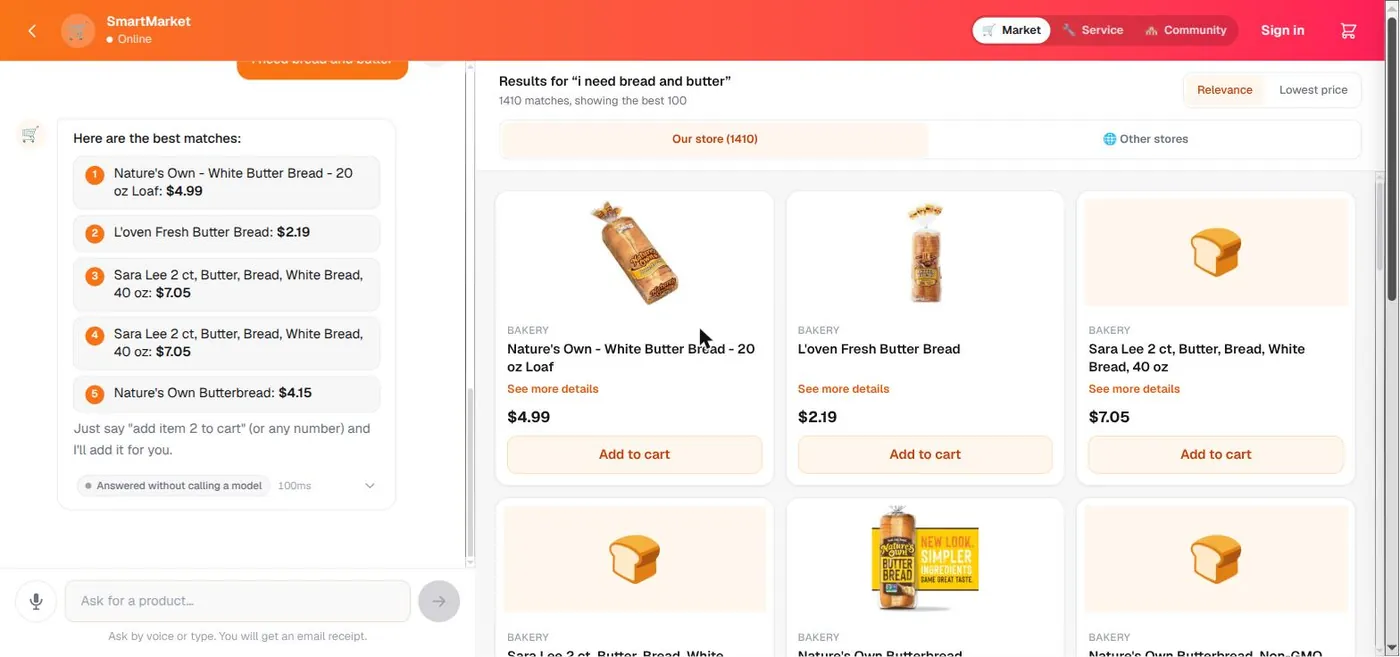
Three production AI assistants on one shared architecture. Retrieval over a vector store, with the backend owning all state, search and money math so the model only classifies intent and phrases the reply.
- SmartMarket
- SmartService
- SmartCommunity
- FastAPI
- MySQL
- pgvector
- Gemini
- Next.js
- AWS
Firefly.online, off the cloud
Moved an IoT SaaS platform off AWS onto self managed bare metal with a blue green cutover. PostgreSQL, Redis persistence and object storage all migrated while customers stayed online.
- Zero downtime
- Blue / green
- PostgreSQL
- Redis
- Nginx
- Grafana
- Prometheus
Mediatiz Foundation
Ran the AWS estate behind an LMS and mobile app serving over a million users at 20K to 30K concurrent requests, then took a third of the bill out of it without touching uptime.
- 1M+ users
- Local LLM tutor
- ECS
- RDS
- CloudWatch
- Lambda
- GitHub Actions
NextLab
A pathology lab management platform running as a commercial product: patient intake, test templates, branded PDF reports, billing, commissions and analytics, sold on five subscription tiers to labs across Pakistan.
- Four actor types
- Billing and commissions
- Django REST
- Next.js 14
- PostgreSQL
- Docker
- Celery
GitOps platform
ArgoCD App of Apps over Helm charts with per environment values, drift detection every three minutes and self healing. CI tags each image by commit SHA and writes the override back, so services roll independently.
- Polyglot, 4 languages
- Self healing drift
- Kubernetes
- ArgoCD
- Helm
- Terraform
- Prometheus
Things that were not what they looked like
The symptom is never the cause. These are real, and the second column is what it actually was.
A GPU worker joined the cluster, reported ready, and failed the first request anyway.
GPU inference platformA race with the device plugin. The node was schedulable before the GPU was actually claimable, so Kubernetes placed work on a card that was not there yet.
The health check itself was causing the failure it was looking for.
GPU inference platformVerification logic held the GPU while the workload tried to start. Two processes, one card, and the check always won because it ran first.
A rebuilt worker came back and still could not talk to anything.
GPU inference platformFirewall state outlived the machine it belonged to. The rules referenced an address the replacement no longer had, and nothing reported an error.
One page took 45 seconds. Every time. Never 44, never 46.
Conversational commerce platformA dependency pointing at a host decommissioned weeks earlier. A dead host does not refuse a connection, it swallows it, so every request sat until the timeout expired and fell back. The suspiciously round number was the timeout, not the work.
The database kept dropping the connection mid-query, seemingly at random.
Conversational commerce platformThe search path re-read all 25,631 product rows and 206 MB of vectors on every single message. Not a network fault. The query was simply too greedy to finish.
Nightly backups had been failing for months. Nobody had noticed.
Multi-tenant lab platformA cron job that exited non-zero into a void. A backup that never runs looks exactly like a quiet night, which is why the absence of alerts is not the same as the presence of health.
Edits to an nginx site file changed nothing, however many times it was reloaded.
Client server estateThe file in sites-enabled was a regular file, not a symlink. Somebody had copied it years earlier. Every edit landed in sites-available and was read by no one.
Where this came from
- Jun 2026 — now
Platform Engineer, AI Infrastructure · Ccript Agency
Built a Kubernetes native platform for deploying, scaling, monitoring and benchmarking LLMs on GPU with vLLM. Migrated a multi brand franchise reporting platform off a third party dashboard onto a native presentation layer, then repaired the KPI accuracy, filtering, location mappings and BigQuery reconciliation underneath it. GCP native monitoring, logging and operational runbooks.
- Oct 2025 — Apr 2026
DevOps Engineer · Mediatiz Foundation
Owned the AWS estate for an LMS and mobile app at 1M+ users. Cut spend 30%, built the CI/CD for four codebases, and shipped a self hosted LLM tutor to keep student data in house.
- Dec 2023 — Oct 2025
DevOps Engineer · Poshmaal Technologies
Led the AWS to on premises migration of an IoT SaaS platform, then rebuilt its dev, staging and production environments with full stack observability and a K3s GitOps cluster for ERP workloads.
- Dec 2021 — Nov 2023
DevOps Consultant, freelance · Fiverr & Upwork
Twenty plus containerisation, CI/CD and server infrastructure projects for small business clients. Docker deployments, GitHub Actions, nginx and Certbot, Ansible for repeatable provisioning, and self hosted Kubernetes with Ingress, HPA and RBAC where it was warranted.
- BS Software Engineering, FAST-NUCES Islamabad, 2020 to 2025
- AWS Solutions Architect and CKA in progress
- RocketDevs vetted talent
Have a platform that costs too much, breaks too often, or needs an AI layer that actually reaches production?
abad.naseerfast@gmail.comOpen to contract and full-time work. I usually reply within a few hours.